 The highest tagged major version is


 README

treehouse



Manage worktrees without managing worktrees.
Are you still only working on one task at a time? Are you manually juggling between a few clones of the same repo?
Or... are you starting a new worktree for every agent session, losing all your installed dependencies and build cache each time, and wondering why your agents are slow?
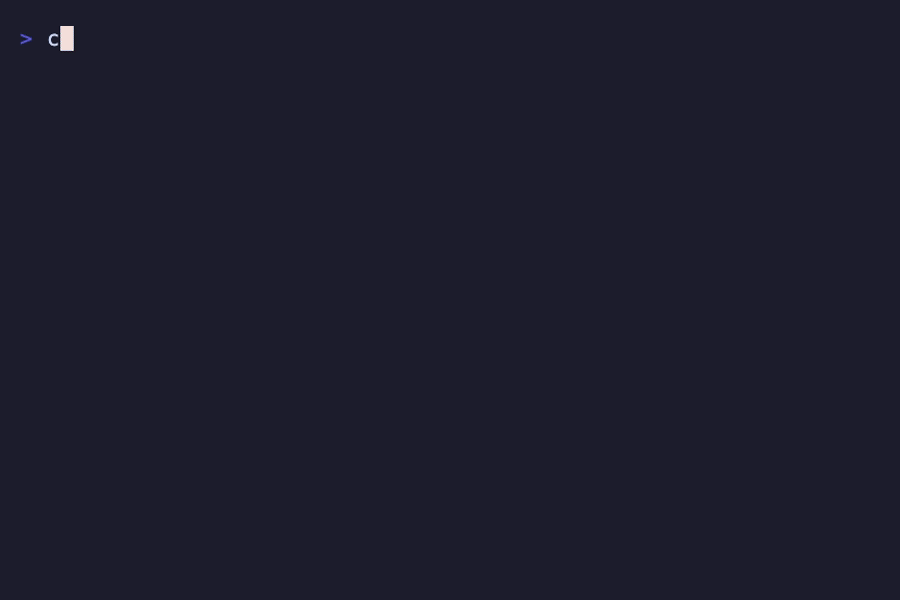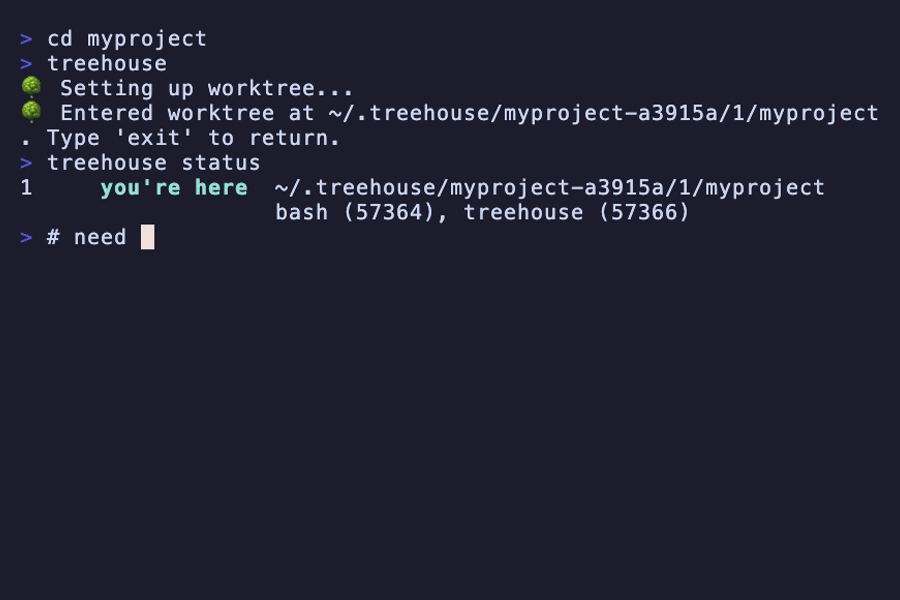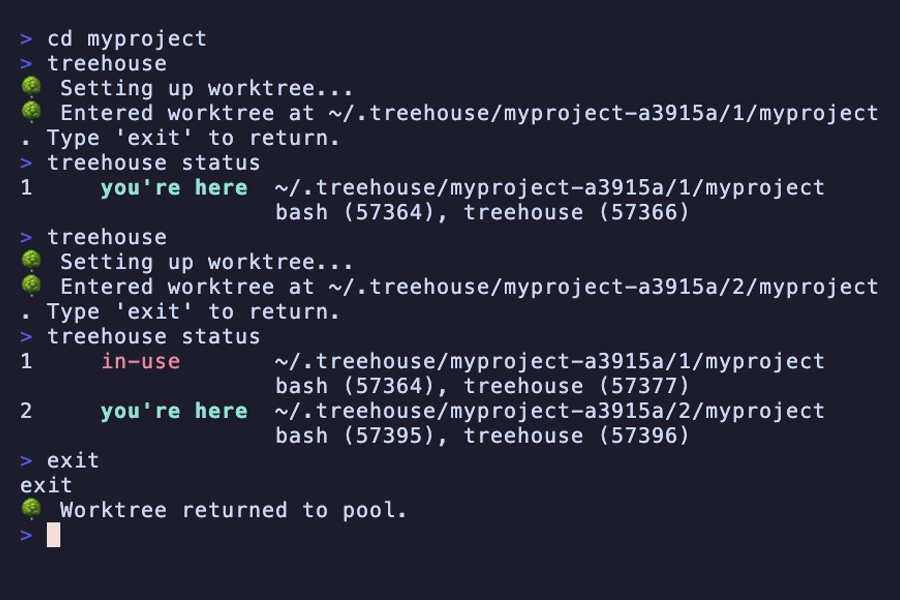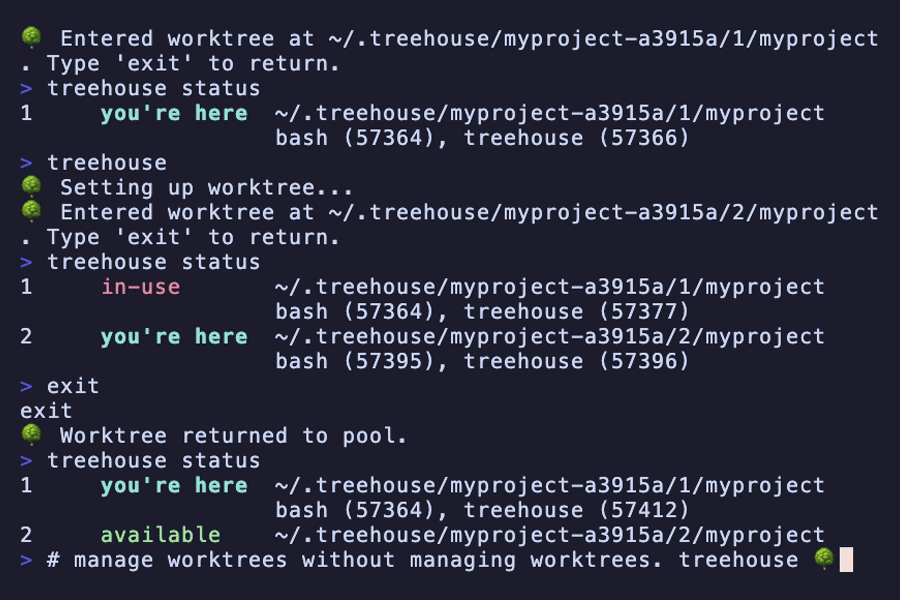
Treehouse helps you manage a pool of reusable, isolated worktrees so each of your agents gets its own environment instantly — no cloning, no conflicts, no coordination overhead.
- Instant isolation —
treehouseputs you into a clean worktree with zero hassel. - Reusable worktrees — worktrees are preserved in a pool when you're done, with dependencies and build cache intact, ready for the next agent.
- Conflict-free — automatic detection of in-use worktrees and your agents never step on each other's toes.
Quick Start
$ cd myproject                 # start in your repo as usual
$ treehouse                    # get a worktree and drop into a subshell
🌳 Entered worktree at ~/.treehouse/myproject-a1b2c3/1/myproject. Type 'exit' to return.

# You're now in an isolated worktree.
# Run your AI agent, make changes, do whatever you need.

$ exit                         # exit the subshell when you're done
🌳 Terminated lingering processes: opencode (pid 12345)
🌳 Worktree returned to pool.
Install
macOS / Linux
curl -fsSL https://kunchenguid.github.io/treehouse/install.sh | sh
Windows (PowerShell)
irm https://kunchenguid.github.io/treehouse/install.ps1 | iex
Nix
nix run github:kunchenguid/treehouse
Or add to your flake inputs:
treehouse = {
  url = "github:kunchenguid/treehouse";
  inputs.nixpkgs.follows = "nixpkgs";
};
Go
go install github.com/kunchenguid/treehouse@latest
From source
git clone https://github.com/kunchenguid/treehouse.git
cd treehouse
make install
How It Works
Treehouse manages a pool of git worktrees per repository, stored under the configured treehouse root.
The default treehouse root is ~/.treehouse/.
  treehouse
      │
      ▼
  Find repo root
      │
      ▼
  git fetch origin
      │
      ▼
  ┌────────────────────────────────────┐
  │  Scan pool for available worktree  │
  │  (not in-use, not dirty)           │
  └──────────┬─────────────────────────┘
             │
        ┌────┴────┐
        │  Found? │
        └────┬────┘
         yes/ \no
           /   \
          ▼     ▼
   Reset to   Create new worktree
   latest     (detached HEAD at
   default    latest default
   branch     branch)
              & add to pool
          \   /
           \ /
            ▼
  Spawn subshell in worktree
  (agent works here)
           │
           ▼
     exit subshell
           │
           ▼
  Terminate lingering worktree
  processes, reset worktree,
  & return to pool
  (ready for next agent)
- Detached HEAD — worktrees use detached HEAD mode, reset to whichever of the local or remote default branch is further ahead, avoiding branch name conflicts entirely.
- No daemon — all operations are inline CLI commands. No background processes, no state to get corrupted.
- In-use detection — treehouse scans running processes and short-lived owner reservations to determine which worktrees are in-use. Reservations are persisted only while
get,destroy, andprunelifecycle work is running. - Dirty detection - treehouse treats tracked changes and untracked files as dirty, even when repository config hides untracked files from normal
git statusoutput. - Safe pruning -
treehouse pruneremoves only idle managed worktrees whose HEAD is already merged into the default branch and whose working tree is clean.treehouse prune --allapplies the same safety checks across every managed pool under the user-level treehouse root. It is a dry run unless you pass--yes.
CLI Reference
| Command | Description |
|---|---|
treehouse |
Get a worktree and open a subshell (alias for get) |
treehouse get |
Acquire a worktree from the pool |
treehouse status |
Show pool status (highlights your current worktree) |
treehouse return [path] |
Terminate lingering worktree processes and return it to the pool |
treehouse prune |
Dry-run removal of stale idle worktrees in the current repo pool |
treehouse prune --all |
Dry-run removal of stale idle worktrees across every managed pool |
treehouse destroy [path] |
Remove a worktree from the pool |
treehouse init |
Create a default treehouse.toml config file |
treehouse update |
Update treehouse to the latest version |
Flags
| Command | Flag | Description |
|---|---|---|
return |
--force |
Clean, reset, and return without prompting |
prune |
--yes |
Delete stale idle worktrees instead of doing a dry run |
prune |
--all |
Sweep every managed pool under the user-level treehouse root |
prune |
--global |
Alias for --all |
destroy |
--force |
Force destroy even if in-use |
destroy |
--all |
Destroy all worktrees in the pool |
Pruning stale worktrees
treehouse prune is a dry run by default.
It lists stale idle managed worktrees that would be deleted and shows the reclaimable disk space.
Pass treehouse prune --yes to delete those worktrees.
By default, prune only inspects the current repository's pool and must be run inside a git repo.
Pass treehouse prune --all or treehouse prune --global to inspect every managed pool under the user-level treehouse root from any directory.
Global prune reads the user-level config and hooks, derives each worktree's owning repository from git metadata, then fetches and checks merge safety against that repository.
Pass treehouse prune --all --yes to delete only the globally safe candidates.
Prune ignores worktrees that are currently in use or reserved by another lifecycle operation.
It skips idle worktrees that are unsafe to remove and prints the skip reason, such as uncommitted tracked or untracked changes, or a HEAD commit that is not merged into the default branch.
When origin exists, prune fetches it and proves each HEAD against the current remote default branch tracking ref.
Without origin, prune uses the local default branch ref.
Configuration
Create a repo config file with treehouse init, or add one manually:
Repo-level: treehouse.toml in the repository root
User-level: ~/.config/treehouse/config.toml
# Maximum number of worktrees in the pool
max_trees = 16

# Optional worktree root directory.
# Empty uses $HOME/.treehouse.
# Relative paths are resolved from the repo root for repo-scoped commands.
# Use an absolute user-level root for treehouse prune --all.
# root = "$HOME/worktrees"
The repo-level config takes precedence for repo-safe settings.
treehouse prune --all can run without a repository, so it uses only the user-level config and does not read per-repo treehouse.toml files while sweeping.
If no config is found, the default pool size is 16.
Hooks
You can run commands automatically at worktree lifecycle points by adding a [hooks] section to the user-level config at ~/.config/treehouse/config.toml.
Hooks in repo-level treehouse.toml are ignored for safety.
[hooks]
post_create = ["./scripts/setup-venv.sh"]
pre_destroy = ["./scripts/teardown.sh"]
post_createruns after a worktree is provisioned or reset and right beforetreehouse gethands it to you.pre_destroyruns before a worktree is removed bytreehouse destroy,treehouse destroy --all, ortreehouse prune --yes.
Commands in each list run sequentially in the worktree directory, via the OS shell (/bin/sh -c on Linux/macOS, %COMSPEC% /c on Windows).
If a command exits non-zero, treehouse logs the command, exit code, and stderr, then continues with the remaining commands.
A failing hook does not fail the overall get, destroy, or prune operation.
Development
make build          # Build the binary
make test           # Run tests
make lint           # Run gofmt + go vet
make dist           # Cross-compile for all platforms
make install        # Install to $GOPATH/bin or /usr/local/bin
make clean          # Remove build artifacts
 Documentation


There is no documentation for this package.
 Source Files
 Directories